


Umay AI Markdown
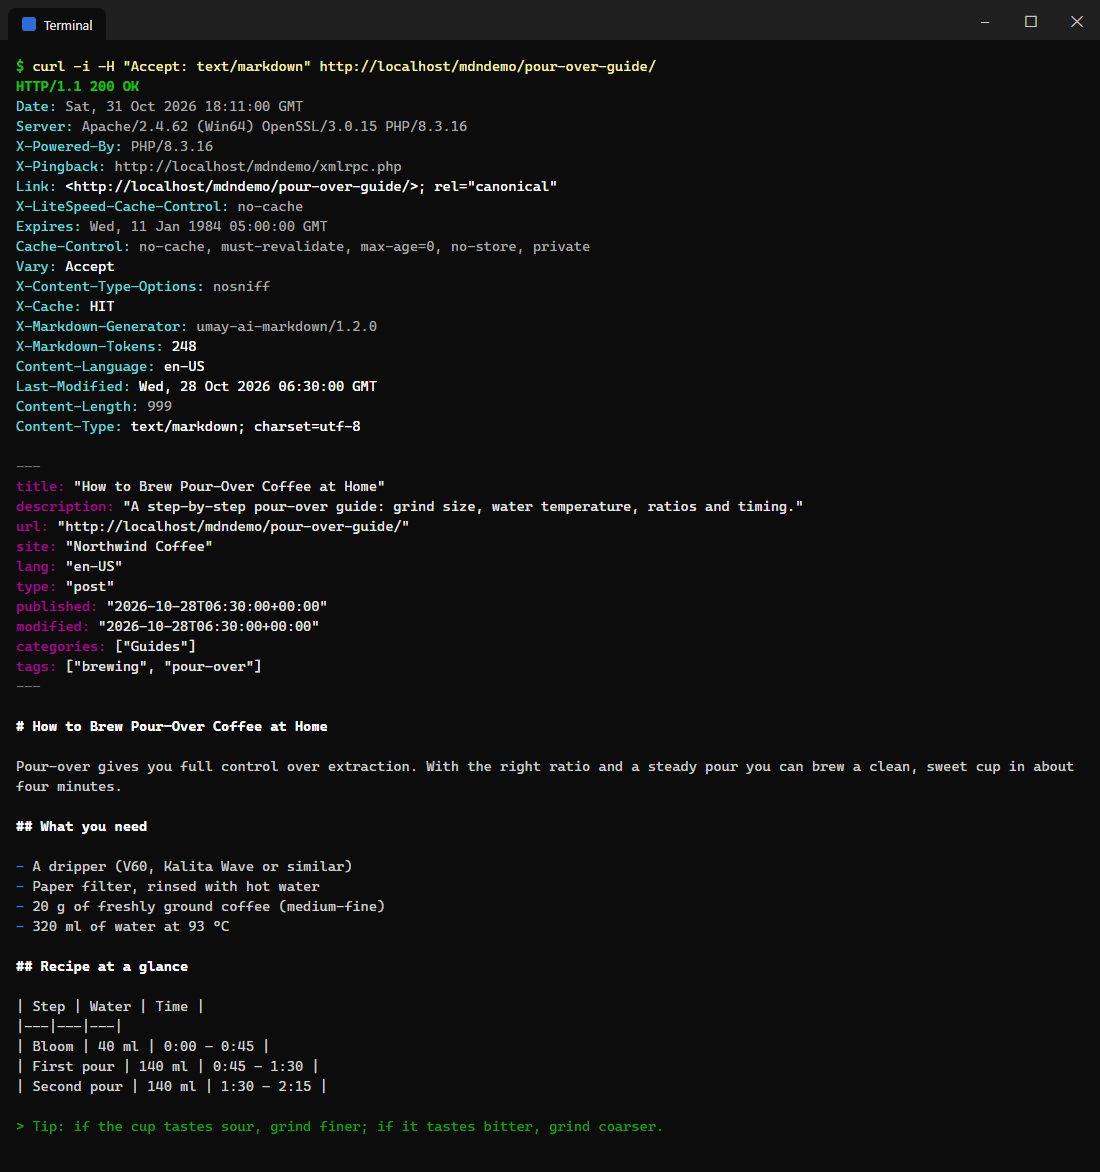
Markdown served to an AI agent that sends <code>Accept: text/markdown</code>: HTTP headers, YAML front matter with the page's metadata, and the post as clean Markdown with its list, table and quote.
AI agents and assistants (ChatGPT, Claude, Perplexity, Gemini, coding agents such as Claude Code) read Markdown far more efficiently than HTML: no menus, scripts or styles, a fraction of the tokens. Umay AI Markdown gives every public page of your site a clean Markdown version and makes it easy for agents to find.
Browsers, search engines and every client that does not ask for Markdown receive your normal, unchanged HTML. There is no settings page and no external service.
Three ways agents get Markdown
- Content negotiation — a request for any page with
Accept: text/markdownreceives Markdown on the same URL. - .md URLs —
/your-post.mdreturns the Markdown of/your-post/, and/index.mdthe home page. Every HTML page advertises its twin with<link rel="alternate" type="text/markdown">and a matchingLinkheader. These URLs also work behind page caches and CDNs. -
/llms.txt — an automatically generated llms.txt index of your pages, posts and public custom post types, each linked to its
.mdURL with its excerpt. An optional/llms-full.txtcontains the full Markdown of every entry..md URLs and
/llms.txtneed pretty permalinks (Settings > Permalinks, anything but “Plain”).
What agents receive
Each Markdown document starts with YAML front matter (title, description, canonical URL, site, language, post type, author, published and modified dates, featured image, categories and tags), followed by the page content as Markdown. Structured data (JSON-LD) that your SEO plugin prints in the page head (Yoast SEO, Rank Math and others) or that sits in the content is appended as fenced json blocks, the same layout Cloudflare’s “Markdown for Agents” uses. Navigation, headers, footers, sidebars, scripts, styles, forms and comment areas are removed; tables become Markdown tables, embedded videos and maps become links, and root-relative links become absolute.
Key features
- Zero configuration — install, activate, done.
- Hybrid extraction:
the_contentfor posts and pages (works with the block editor, Elementor and other builders), DOM extraction of the rendered theme for archives, the home page and taxonomies. - Powered by league/html-to-markdown.
- 12-hour cache per URL, invalidated automatically when content, terms, menus, templates or the theme change.
- Respects WordPress: password-protected, private, draft and missing pages are never served as Markdown. Canonical redirects, login walls, maintenance modes (503) and coming-soon templates apply first.
- Page-cache safe: Markdown responses are never stored by LiteSpeed Cache, WP Rocket, W3 Total Cache and other page caches.
- Agent-friendly headers:
X-Markdown-Tokens(token estimate),Link: rel="canonical",Content-Language,Last-Modified,Vary: Accept, and optionalContent-Signal. - Per-IP rate limit for uncached renders (30 per minute by default).
- No external requests, no telemetry, no database tables.
Filters
umay_mdn_bypass(bool, default false) — return true to skip Markdown for the current request.umay_mdn_md_suffix(bool, default true with pretty permalinks) — serve and advertise.mdURLs.umay_mdn_llms_txt(bool, default true) — serve/llms.txt.umay_mdn_llms_full(bool, default false) — serve/llms-full.txt.umay_mdn_llms_post_types(string[]) — post types listed in llms.txt.umay_mdn_llms_limit(int, default 100) — entries per post type in llms.txt.umay_mdn_content_signal(string, default empty) — Content-Signal preference, e.g.search=yes, ai-input=yes, ai-train=no.umay_mdn_front_matter(array) — modify the front matter fields.umay_mdn_converter_options(array) — league/html-to-markdown options.umay_mdn_cache_ttl(int, default 43200) — cache lifetime in seconds (minimum 60).umay_mdn_rate_limit(int, default 30) — uncached renders per IP per minute.umay_mdn_vary_html(bool, default true) — sendVary: Accepton HTML responses.umay_mdn_client_ip(string) — client IP used for rate limiting (for sites behind a proxy or CDN).umay_mdn_layout_template(bool, $template) — whether a template that a plugin swapped in only changes the layout (page-builder templates by default), so the post content is still read directly.umay_mdn_llms_include(bool, $post) — return false to leave a post out of llms.txt and llms-full.txt.umay_mdn_ignored_cookies(string[]) — cookie name prefixes that do not personalize pages (analytics, CDN); any other cookie makes a response uncacheable.
Action: do_action( 'umay_mdn_flush' ) clears the Markdown cache.